What does an AI engineer do?
00:00:00 — The Agent Adoption Funnel and Rising Abstractions
Just tweeted something this weekend where he kind of he kind of talks about this growing gap between basically folks at the frontier who are running thousands of agents and swarms of always-on agents. And he really kind of drops this funnel where six billion plus users have maybe touched or interfaced with an LLM, one to two billion, or maybe like casual, free-tier users, 20 million or professionals who have maybe started using it for more, taking some piece of work that would have taken weeks down to days. But really, those at the frontier labs are just super small percentages, like five thousand users are the ones who are running thousands and thousands of agents at once.
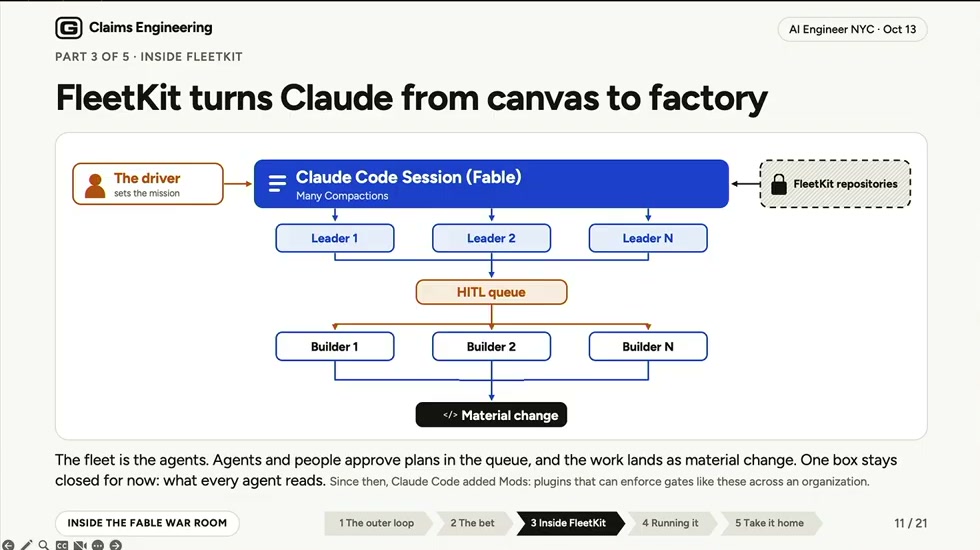
And as I look at this, it really is. I mean, he's kind of dropped a bit of the fun. I mean, the first question anyone looks at this is that, where am I on this? And you know he's kind of drawn out a bit of a roadmap of how does everyone get to in the next couple of years one of those 5,000 users, we're running thousands of agents, and this has been happening I think for a couple of decades now, where the abstraction layer has gotten higher and higher. I mean, definitely faster in the last couple of years, but we've gone from engineers writing higher-level abstraction languages to, I mean, just copy-pasting code, using local agents to using cloud agents to really the expectation now is how do all of us start running a team of agents or factories of agents internally and build toward that?
00:01:43 — Building the Engineering Loop Over Individual Features
And what this has led to is essentially what is the then and now of what an AI engineer is, and this is — this is this is a bit, I think, of a roadmap for some, but I think internally, this is what we've already started to kind of push towards.
As an AI engineer, your job is no longer to just write the feature, write a bad feature. It's about how do you build the loop to write that feature. It's no longer about, you know, just reading the diff and actually doing code review. It's actually how do you set up systems and agents to do the code reviews and having to write emails to actually do the non-deterministic to review those non-deterministic paths.
It's actually no longer even about just setting up metrics and software kind of telemetry, but it's actually how do you have agents go through and read the observability data and have agents actually consumed that telemetry to find patterns. And so this loop that we've kind of been talking about, which is the build, eval, ship, you monitor, you improve it — well, the AI engineer is now actually responsible not just for doing each of those steps, but how do you build the loop that does the that actually does each of those steps.
00:02:55 — Signal: Always-On Agents Reading Production Traces
And it arises, one of the things we've rolled out in our product, and I'm going to talk about a bit of what we've learned in building this, is we built Signal to actually run this loop for AI engineers. What Signal does is that signal actually looks at all of the traces. It reads the telemetry, it identifies patterns in that telemetry, and it can actually put up a fix or a PR if it has access to the repo, and signal signals is always on agent, so this is an example of how signal starts, but it actually starts off by just reading the traces, super simple example, but it goes through reads, you know, all this configurable that a certain volume of traces that came in, and some cadence it reads it and then the goal is to actually identify issues from that telemetry data.
It has to keep track of issues that it's previously seen, so we have to consider the memory of, didn't see something before that it thought was an issue. Did something seem like an issue, but it wasn't actually captured? And now, as it collects more data, it actually thinks it's much more of a critical issue, and so Signal actually starts off by reading the traces to identify problems.
00:04:10 — Observability Triggers and Isolated Agent Sandboxes
And so, one of the first things that we realized was that the future of who's actually consuming telemetry data has really changed. It's no longer about humans consuming telemetry data. It's not even about humans consuming it and agents kind of taking on the task, but it really is, how do you set up your telemetry data so that agents are the primary consumers of that data? And what that does is that observability data can become the trigger for actually running and triggering these always-on agents, and so the first thing that we're building a team of, a factory of really always on agents is what triggers these agents to wake up or start.
And there can be a variety of triggers for signal. For us, it's configurable to run on an ongoing cadence, so every three hours, six hours, go pull the last, you know X amount of traces, read them, identify problems. It can also be triggered by events, so Slack messages, if some user complains about something. It can be a metric-based trigger, but these are essentially triggers to kick up the agent actually starting. Once the agent actually starts, we have to spend some time figuring out, well, what is what does an agent run actually look like?
For us, we actually pull in all of the contexts and the traces, any additional third-party data, so we allow collecting to APM logs, APM metrics, but all of the third-party telemetry data that we want to pull in, access to the repo, access to the actual, the access to any keys that are needed to actually run this agent, but all of this information is put inside of the sandbox, and this is actually what's started up every time the agent wakes up.
And so the agents trigger. We build a sandbox. We put everything that we need inside of that sandbox. There's a proxy. The only way to get information in and out of the sandbox is by this single proxy, and everything that happens inside that sandbox is actually already getting traced, and every output, so the issues that are generated and created, are all being saved to some kind of memory.
00:06:32 — Durable State, Ephemeral Teardown, and Harness Agnosticism
And so this happens every single time the agent actually runs, every time the agent finishes running. So it swept through all of the traces. It either found something or it didn't. There's what actually stays and what actually gets thrown away. What stays is that if it found any issues, all of the output is actually saved off in some kind of memory, so that the next time an agent gets spun up, it doesn't have to start from ground zero. It has a history of what are the issues that it actually found. The agents are traced, so all of the telemetry data of what the agent called, you know, if it actually put up a PR, all of those things are actually tracked, and any skills that it may have learned while actually doing a run can also get saved to the actual repo.
But the things that go away is the sandbox gets torn down. Any credentials, you know, obviously get removed, the repo access is removed, and so all of the stuff that does it need to be saved, how to get stored down after the run of signal. And we've designed Signal in a way to actually keep this agent and figure durable, so that means that either the if the sandbox fails, or if the harness fails, then it shouldn't have to start everything from scratch in the middle of the run. It should actually just be able to pick up from the step that it failed, and all of the state, so-called was kind of saved off and kind of a memory outside of the sandbox. And so we've designed this to actually be a very durable agent, so that if it fails, you can spin it back up. You can launch a new sandbox, launch a new harness to kind of pick back up where it.
So all of this is essentially the underpinnings of how we build signal to run every single run. Agent gets triggered. Agent gets started. It loaded with all the context, the evidence. It sweeps through the telemetry data. It either finds something or it doesn't. All of that gets save the memory. If something fails in the middle, the agent can get reset up, and we built Signal to also be, you know, agnostic of the model or the harness. So today, Signal supports not just Claude code, which is what we started with, but it also supports Cursor and Codex, and the goal is to actually support all of the major, even the open source harnesses out there, and Signal actually also supports multiple — we'll support kind of multiple models, so even if you're using Claude code, and you can pick any of the models inside the Anthropic family, and this is really important to us because one, it's an awesome way for us to evaluate the quality of the agent every time we spin it up.
It helps us control costs, so we can see, you know, as we use more powerful models, the better quality maybe the PRs are, but can we reduce the quality of the — you know, can we reduce the cost and actually still maintain the rigor and maintain the quality of issues that are actually detected by Signal? So this is something we deeply thought about from first principles when we were designing Signal.
00:09:45 — Aligning Evals with Human Judgment
And this is actually a pretty good segue into what does an AI engineer need to do? Well, an AI engineer really needs to kind of learn how to write emails, and so we actually every time Signal runs, Signal finds an issue, it puts up the PR. Well, there's evals that are run on top of the agent to test that PR. And an email can be as simple as you're testing something as part of your development workflow. You have a dataset. It can be a simple prompt with outputs that you're testing to make sure that there's no regressions.
But these evals can also — they need to be kind of aligned with human judgment, and I argue that this is actually probably where an AI engineer should be spending a lot of their time as they're building the system that actually runs the loop. They should be actually spending time looking at the traces with their agents, identifying what the common errors are. And there's a lot of skills. I think I was hearing Lance yesterday talk about the cloud skill to build evals. We have a skill with the rise, evaluator to actually help you build and write evals as well as align those evals with the human judgment, but this is probably where the shift to defining what is good becomes really, really important for an AI engineer to actually do.
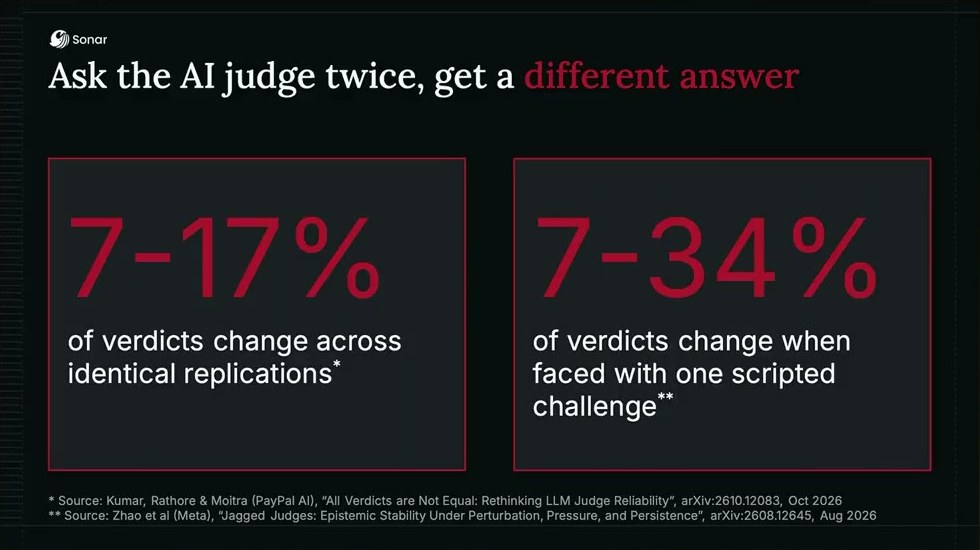
And for a lot of teams, I think we speak with and we work with their question becomes well, how do I trust the evaluator and do I do I really trust that the eval is, you know, is going to capture — how do I trust that it's as good as my judgment? And I think what we spend a lot of our own time doing for our own products is that we actually evaluate the evaluators. We spent a decent amount of time on actually building these data sets, golden tree datasets. We run evals, verify them against the human output, and then try to align to make sure that the judge actually agrees with the human and they're in agreement before we actually ship out a new evaluator. And these e-bells can then be used both in an offline testing as well as in an online testing manner, and this is probably what I would say as an AI engineer is more and more of what the job is becoming.
00:12:10 — Tracing the Agent Factory End-to-End
And so, what I'm going to leave you guys with is as an engineer, you built this agent. You built this agent to actually run, be always on. You run evals before you actually ship it into production. You can ship it, and then once it goes into production, the goal is to actually trace everything. And tracing everything now means not just tracing the agents, but also tracing the coding agents behind the agents that build this. So, you can trace Plot code, you can trace cursors, you can trace codecs, but all of these coding agents can be traced, so you can understand what happened in the factory of agents that you all are building.
And then these agents, that all the traces can then also be evaluated online. So there's an offline evaluation when you're actually testing what your what a new change is, but as it goes into production, these become your online evals that you're running on top of the telemetry data. This for us ends up becoming the new data that then gets pulled back into the agents to read the telemetry data, the evals, and surface up kind of problems inside of the traces. So the system really becomes: How do you go from collect data, evolve that data, run agents on top of it, so that you can find problems and figure out where the gaps are to improve your systems.
00:13:42 — Closing the Gap Between Frontier Labs and Enterprise
So if I go back to kind of the question that we started this whole thing with, is, what does an AI engineer do? I mean, the gap between — I think there's a pretty big gap between what's happening in the labs today and what's happening with a lot of businesses. And some of it could just be the data inside of businesses are a lot more messy than what is very constrained and testable inside of a lab, but AI engineers are kind of the role to close that gap.
And I think it really starts with tracing everything, tracing the agents you're actually building, running evals, being able to learn how to test these test these products that we're really building. And then, how do you build the system so that agents can actually improve from the telemetry that's actually being collected, so that you're no longer just building individual features, but you're actually building the system to improve to improve your products.
If you want to learn more, come check out Boot. You can check out Signal. Learn more. But thank you so much for Signal.
The current program has finished its run. Please collect your belongings and proceed through the main doors for your next schedule.