Everything Is a Rollout — Alex Shaw + Ryan Marten, Terminal-Bench, Harbor, Laude Institute
Everything Is a Rollout — Alex Shaw + Ryan Marten, Terminal-Bench, Harbor, Laude Institute
Summary
Alex Shaw and Ryan Marten of the Laude Institute make the case that agent development is not software engineering anymore — it’s machine learning. They open with a nostalgic 2018 tweet about reviewing a 400-line pull request, then contrast it with a Francois Chollet quote: “agentic coding is a form of machine learning… generated code is best treated as a black box artifact whose behavior and generalization should be managed via empirical evaluation.” Ryan demonstrates this literally, showing a 2018 regex-based phone-number extractor next to its 2026 LLM-based equivalent — the same task, but one is deterministic and one isn’t. From there they map the entire ML toolkit onto agent-building: training data becomes environments, validation sets become evals, model weights become skills/prompts/tools, loss functions become environment rewards, backprop becomes context-based optimization (JEPA, or just running a coding agent in a loop), and overfitting becomes reward hacking.
The core of the talk is Harbor, the Laude Institute’s open-source framework for running “rollouts” — the universal unit of agent evaluation. A rollout takes an instruction and a sandbox, hands the sandbox to an agent, lets it run to a stopping condition, hands the resulting trajectory to a verifier, and aggregates the reward. Harbor specifies this as a standard file-directory format (now widely adopted across the environment space), runs rollouts for any agent/model/sandbox/task combination in parallel, and hosts a registry of 300-400 training and eval environment sets. Alex argues every company that uses computers should be building these evals, quoting Satya Nadella’s “start with the eval that matters” and walking through four categories people actually build for: evaluating how well agents build your product (e.g., Ramp’s internal SWE-bench), how well agents use your product (headless-mode readiness), how well agents power product features, and how well agents automate internal processes.
The back half is a tour of what people have built on Harbor: a live demo of Harbor Exec doing “agentic map-reduce” over a batch of Codex sessions (cheap model for the map step, Claude for the reduce step, producing a feedback.md of recurring mistakes), plus a rapid-fire list of ecosystem projects — Frontier Suite, Handshake’s Banker Toolbench, Cognition migrating its evals to Harbor, the RuneScape-playing RuneBench, Scale’s Atlas suite, Poolside’s training evals, Kevin Goo’s AutoAgent, Afterquery post-training, Cognition’s Frontier Code, LangChain’s DeepAgents integration, and Snorkel’s just-released Senior SWE-bench. The pitch throughout is that Harbor is trying to be a common, interoperable language for agentic environments so that data — and therefore progress — moves as fast as possible.
Highlights
”Software engineering was when you knew what the code would do before you ran it”
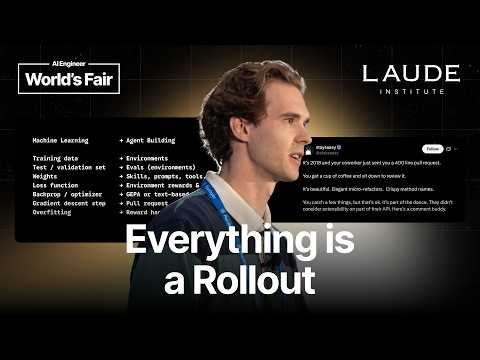
“It will probably say, the history books will probably say a lot of things. But I think one thing for sure that they’ll say is software engineering was when you knew what the code would do before you ran it.” — Alex Shaw, 2:30
Clip command
yt-dlp --download-sections "*2:30-2:56" "https://www.youtube.com/watch?v=jRCpXUjz4CI" --force-keyframes-at-cuts --merge-output-format mp4 -o "software-engineering-2018.mp4"”Agent performance itself is best treated as a black box artifact”
“So now let’s come back to Francois’ tweet and let’s update it a little bit, we’ll generalize it. So he says agentic coding and my claim is well just agents in general are a form of machine learning and then he says generated code is best treated as a black box artifact and I say agent performance itself is best treated as a black box artifact.” — Ryan Marten, 5:00
Clip command
yt-dlp --download-sections "*5:00-5:26" "https://www.youtube.com/watch?v=jRCpXUjz4CI" --force-keyframes-at-cuts --merge-output-format mp4 -o "agent-performance-black-box.mp4"”Who needs evals? Every single company that uses computers”
“Uh, so who needs evals? Now that we understand how to make them, we understand how to use them, well now who should actually be doing this? And the answer is every single company that uses computers.” — Alex Shaw, 11:35
Clip command
yt-dlp --download-sections "*11:35-12:00" "https://www.youtube.com/watch?v=jRCpXUjz4CI" --force-keyframes-at-cuts --merge-output-format mp4 -o "who-needs-evals.mp4"”As soon as you have an eval the power is now in your hands”
“Start with the eval that matters and your ability to grade that outcome and then say I welcome all models. So I like that last line because what he goes to say is that as soon as you have an eval the power is now in your hands. You can consider every single model. You don’t have to trust brand. You don’t have to trust somebody else’s eval.” — Ryan Marten, 12:00
Clip command
yt-dlp --download-sections "*12:00-12:12" "https://www.youtube.com/watch?v=jRCpXUjz4CI" --force-keyframes-at-cuts --merge-output-format mp4 -o "power-in-your-hands.mp4"Live demo: Harbor Exec as agentic map-reduce over Codex sessions
“So I’m saying Harbor Exec input is all of my Codex sessions from the June 20s… I do the map step with Cursor CLI because it’s cheap and fast. And then I do the reduce step with Claude 3.5 because I want it to have like an accurate summary.” — Alex Shaw, 17:13
Clip command
yt-dlp --download-sections "*17:13-18:32" "https://www.youtube.com/watch?v=jRCpXUjz4CI" --force-keyframes-at-cuts --merge-output-format mp4 -o "harbor-exec-demo.mp4"RuneBench: benchmarking how well agents play RuneScape
“This RuneBench, this is one of my favorites, it’s like a benchmark to measure how well agents can play RuneScape.” — Alex Shaw, 19:36
Clip command
yt-dlp --download-sections "*19:19-19:58" "https://www.youtube.com/watch?v=jRCpXUjz4CI" --force-keyframes-at-cuts --merge-output-format mp4 -o "runebench.mp4"Key Points
- Speaker intro (0:15) - Alex Shaw of the Laude Institute introduces Harbor, an agent evaluation and RL environment framework.
- 2018 nostalgia trip (0:41) - Avengers Infinity War, GPT-1’s quiet release, TikTok’s rebrand, and AirPods as cultural markers of “old” software engineering.
- The 400-line PR tweet (1:34) - A nostalgic tweet about reviewing elegant, deterministic pull requests sets up the contrast with agentic code.
- Software engineering defined by predictability (2:30) - The old era was defined by knowing what code would do before running it.
- Francois Chollet’s tweet (2:56) - “Agentic coding is a form of machine learning… generated code is best treated as a black box artifact.”
- 2018 regex vs. 2026 LLM call (3:30) - Ryan Marten live-codes a phone-number extractor two ways to show the shift from deterministic to probabilistic.
- ML-to-agent-building mapping (5:26) - Training data → environments, validation set → evals, weights → skills/prompts/tools, loss function → environment rewards, backprop → JEPA/agent loops, gradient step → pull request, overfitting → reward hacking.
- Agent-building is already bigger than ML ever was (6:59) - The number of people building agents already dwarfs the number who ever did traditional ML, and it’s still growing.
- What is an environment (7:59) - An instruction, a sandbox for the agent to act in, and a verifier to check whether the task was done.
- Harbor’s standard directory format (8:31) - A file-layout convention for specifying environments that’s become relatively standard across the environment space, enabling interoperability.
- Anatomy of a Harbor rollout (9:21) - Sandbox → agent runs to a stopping condition → trajectory → verifier → reward → aggregated eval result.
- Harbor’s three-part definition (10:44) - A format for specifying agentic environments, an open-source parallel-rollout framework for any agent/model/sandbox/task, and a registry of 300-400 eval sets.
- Who needs evals (11:35) - Every company that uses computers, because AI can automate part of any computer-based process.
- Satya Nadella’s eval-first quote (12:00) - Once you own the eval, you can evaluate any model without trusting brand names or public benchmarks.
- Four categories of evals people build (12:34) - How well agents build your product (e.g., Ramp SWE-bench), how well agents use your product, how well agents power product features, and how well agents automate internal processes.
- Harbor CLI demo (14:26) - Running Terminal-Bench 2.1 with Codex/GPT-3.5 at 64x parallelism, with fire-and-forget server launches coming soon.
- The data-selling market (15:21) - A multi-billion-dollar market exists around experts specifying tasks and selling them to labs as training data.
- “Prod rollouts” / agentic map-reduce (15:51) - Harbor isn’t only for eval/training — it can run agents at scale for real production work, aggregating results across sandboxes.
- Harbor Exec live demo (17:13) - Map-reduce over 32 Codex sessions: Cursor CLI for the cheap map step, Claude 3.5 for the accurate reduce step, producing a recurring-mistakes feedback.md.
- SFT and RL from rollouts (18:32) - Trajectories feed supervised fine-tuning; rewards plus trajectories feed reinforcement learning, including a Thinker integration.
- Ecosystem rapid-fire (19:19) - Frontier Suite, Banker Toolbench (Handshake), Cognition’s eval migration, RuneBench, Scale’s Atlas suite, Poolside, AutoAgent, Afterquery, Frontier Code, LangChain DeepAgents, and Snorkel’s Senior SWE-bench (released the same day).
- Closing call to action (20:28) - Harbor is actively hiring; DM Alex Shaw on Twitter to get involved or find the docs.
Mentions
Companies
- Laude Institute (0:15) - Alex Shaw and Ryan Marten’s employer; builds Harbor.
- Databricks (6:59) - Cited as an example of how large a company machine learning tooling spawned.
- Ramp (12:34) - Built an internal “Ramp SWE-bench” on its own codebase to pick the best coding agent.
- HubSpot (13:21) - Cited as a developer-first company well-positioned for agent-usability evals.
- Stripe (13:21) - Same, developer-first / headless-mode example.
- Handshake (19:19) - Built Banker Toolbench, an investment-banking benchmark, on Harbor.
- Cognition (19:31) - Migrated all its evals to Harbor (per Swyx) and released Frontier Code.
- Scale (19:43) - Launched its Atlas suite on Harbor.
- Poolside (19:47) - Uses Harbor for all model-training evaluations.
- Afterquery (19:58) - Post-trained a model using Harbor.
- LangChain (20:05) - Integrated DeepAgents and its sandboxes into Harbor.
- Snorkel (20:11) - Released Senior SWE-bench, a Harbor benchmark, the same day as the talk.
- Modal (18:00) - Cloud sandboxing platform used in the Harbor Exec demo.
Products & Technologies
- Harbor (0:15) - Open-source framework for running agent rollouts across any agent, model, sandbox, and task.
- Terminal-Bench (14:26) - Benchmark run via the Harbor CLI in the demo (version 2.1, with Codex/GPT-3.5).
- Harbor Exec (16:34) - Harbor’s map-reduce feature for running agents over batches of arbitrary data; slated to be deprecated soon.
- JEPA (6:00) - Cited as a context-text-based optimization algorithm, the “backprop” analog for agents.
- Codex (14:26) - Coding agent used in the Terminal-Bench demo and the Harbor Exec map step.
- Cursor CLI (17:13) - Used for the cheap/fast map step in the Harbor Exec demo.
- RuneBench (19:36) - Community-built Harbor benchmark for measuring agent performance in RuneScape.
- AutoAgent (19:52) - Self-optimizing agent built by Kevin Goo that only needs a Harbor eval plugged in.
- DeepAgents (20:05) - LangChain’s agent framework, newly integrated with Harbor sandboxes.
- Senior SWE-bench (20:11) - Snorkel’s benchmark for agent performance under ambiguity with behavioral feedback.
People
- Alex Shaw (0:15) - Speaker; creator of Harbor, Member of Technical Staff at Laude Institute.
- Ryan Marten (0:12) - Speaker; builds Harbor, works on Terminal-Bench and OpenThoughts-Agent.
- Francois Chollet (2:56) - Tweet quoted as the framing device for “agent performance as black box artifact.”
- Satya Nadella (12:12) - Quoted from the Applied Compute podcast on building agentic systems around evals.
- Swyx (19:31) - Cited saying his team at Cognition migrated all evals to Harbor.
- Kevin Goo (19:52) - Created AutoAgent, a self-optimizing agent built on Harbor evals.
Surprising Quotes
“Your gradient descent step looks like a pull request into your repo. And overfitting looks like reward hacking or also just overfitting.” — Alex Shaw, 6:29
“Already, the number of people using and building agents is probably magnitudes larger than the number of people that ever were doing machine learning, and that trend will only continue.” — Alex Shaw, 6:59
“I think we have like three or four hundred eval sets by now. And in fact, I think two or three benchmarks even came out today that run with Harbor.” — Alex Shaw, 11:18
“Kevin Goo created AutoAgent, which is a self-optimizing agent that all you have to plug in is a Harbor eval.” — Alex Shaw, 19:52
“And then actually just today, Snorkel released Senior SWE-bench, which is a benchmark for measuring how well agents can function under ambiguity with behavioral feedback.” — Alex Shaw, 20:11
Transcript
Ryan Marten: 0:12 Next up, Alex Shaw.
Alex Shaw: 0:15 Awesome, thank you so much. Uh, so yeah, like he said, my name is Alex Shaw, I work at Latent Institute. And I’ll be speaking today about Harbor, which is an agent evaluation and RL environment framework. And the title of my talk is Everything is a Rollout, and I think you’ll see as I get into it why we titled the talk that way.
Alex Shaw: 0:41 But first, I want everybody to come travel back in time with me to the year 2018. So eight years ago, and we’re going to talk about some of the things that were going on in 2018.
Alex Shaw: 0:54 So, probably you’re going to see Avengers Infinity War later today, the second one is just getting released. GPT-1 was just released and you probably didn’t even notice, although maybe some people did. Musically, this random startup was about to rebrand to a product called TikTok. And you might have just learned about AirPods when you saw somebody walking around with headphones that had no cord.
Alex Shaw: 1:26 So what about software engineering? What did software engineering look like in 2018?
Alex Shaw: 1:34 We’re going to read this tweet from Stay Sassy Sassy with two ‘a’s, about what it was like to write code in 2018. So it says, ‘It’s 2018 and your coworker just sent you a 400-line pull request. You get a cup of coffee and sit down to review it. It’s beautiful, elegant micro-refactors, crispy method names. You catch a few things but that’s okay, it’s part of the dance. They didn’t consider extensibility on part of their API. Here’s a comment buddy.’
Alex Shaw: 2:07 And this is actually just part of the tweet so it keeps going, you should look it up if you want. And it’s obviously written humorously, but the thing is it does feel a little bit nostalgic, just like some of these other things that were going on in 2018. Now the thing is, this only changed maybe six or twelve or eighteen, if you’re a very early adopter, months ago, but it already feels like the distant past in some ways.
Alex Shaw: 2:30 And I think it’s time to start talking about, well what will the history books say about software engineering? When I say software engineering, I mean that style of 2018 software engineering. It will probably say, the history books will probably say a lot of things. But I think one thing for sure that they’ll say is software engineering was when you knew what the code would do before you ran it.
Alex Shaw: 2:56 So and that brings me then to a different tweet from Francois Chollet, where he says agentic code…
Ryan Marten: 3:00 Agentic coding is a form of machine learning. Generated code is best treated as a black box artifact whose behavior and generalization should be managed via empirical evaluation like with any ML model.
Ryan Marten: 3:13 And that kind of brings us to the next part in this talk, which is to compare and contrast what agent development looks like versus what more traditional software engineering development looks like and why it demands a new set of tools to really understand what’s going on and have confidence and trust.
Ryan Marten: 3:30 Um, so here’s a - here’s a 2018 program right here. Um, so you can tell already the purpose of the program is to extract phone numbers from text and we have a regex right here that uh looks for the phone number and I can say with 100% confidence what will happen if I run this program one million times in a row. Um, so now let’s update it to the 2026 version.
Ryan Marten: 3:58 So, uh I swap out my regex and instead obviously I throw in my model call instead and I say extract this phone number. Um, so in some ways this is actually a more powerful program because uh the regex was actually a little bit brittle. It would have missed any phone number that wasn’t formatted exactly like how it was specified, whereas I’m pretty confident that this program with GPT 5.5 will catch a lot of the phone numbers that are formatted weirdly. Um, however, if I ran this exact program one million times, I’m not 100% confident that it will print the same thing every single time or that I know exactly what it will print. Um, it probably gets it right almost every time. This is a pretty simple task. Um, but uh this is obviously far simpler than the things we’re asking these models to do and the uncertainty only increases as the complexity of the task increases.
Ryan Marten: 5:00 So now let’s come back to Francois’ tweet and let’s update it a little bit, we’ll generalize it. So he says agentic coding and my claim is well just agents in general are a form of machine learning and then he says generated code is best treated as a black box artifact and I say agent performance itself is best treated as a black box artifact.
Ryan Marten: 5:26 And that brings us to our - to our new paradigm. So, uh we know now agent development is more similar to machine learning than it is to software engineering. So what are the things that we should keep an eye out for, the - the tools that you use for machine learning and also the pitfalls in machine learning and what are the analogs for those with agent development? So we have machine learning on the left, agent building on the right. Uh, so training data that now looks like environments. And then your test and your validation set that looks like evals, which if you take off the mask is also actually just environments.
Alex Shaw: 6:00 At least the style that we’ll be talking about today. Weights, your model weights are now skills, prompts, tools, the model, whether you’re picking between models or actually updating the model yourself. Your loss function looks now more like environment rewards and feedback. Your backprop or optimizer is now some context text-based optimization algorithm like JEPA or even just running a coding agent in a loop.
Alex Shaw: 6:29 Your gradient descent step looks like a pull request into your repo. And overfitting looks like reward hacking or also just overfitting. That’s also possible for agent development. So we have these things on the left. There’s, you know, products and libraries and platforms that were built for these purposes. And then for everything on the right, we’re just getting started. So we built Harbor to answer some of these questions.
Alex Shaw: 6:59 We’re building it to answer more of these questions, but other people are also building interesting products and interesting frameworks to help people tighten this loop of agent development. And then something else to consider is that as popular as machine learning was and it spawned some of the largest companies in the world, you have like Databricks which are worth hundreds of billions of dollars. Already, the number of people using and building agents is probably magnitudes larger than the number of people that ever were doing machine learning, and that trend will only continue.
Alex Shaw: 7:36 And now let’s look at the last piece of Francois’s tweet that I want to call out, which is these agent performances should be managed via empirical evaluation. And that brings us to our next question, which is how do I actually evaluate an agent? And this is when we start to get into what Harbor does.
Ryan Marten: 7:59 So the answer, as we already gave away earlier, is environments. That’s your evals and your training data. And what is an environment in this case? Well, we need an instruction. We need some way to tell the agent what it’s supposed to do. And then we need some place for the agent to try to do this thing. And right now all of the agents run on computers and they do stuff on computers, so we’ll put it into a computer, but we’ll put it into a virtual computer, so a sandbox.
Ryan Marten: 8:31 And then we need some way of telling whether or not the agent actually did the thing that we told it to do in the sandbox within some amount of time or other stopping condition. And that’s your verifier, which is like some programmatic tests or rubrics or agent that comes in to see what happened. So in Harbor, you specify this as a file directory. And this specific directory layout has become relatively standard in a lot of the environment space.
Alex Shaw: 9:00 So lots of people have adopted it and used it as a way to specify environments, which is useful because then it can easily pass between hands and becomes interoperable.
Alex Shaw: 9:10 Um, and then, okay, cool, we have a bunch of data now, we’ve implemented a bunch of these environments, now how do I actually use it to start understanding what my agent can and can’t do and how to make it better?
Alex Shaw: 9:21 Um, so that’s a Harbor rollout. And, uh, so what you do is you start with your tasks and then you take it, you start up your sandbox, and then step one, you pass that sandbox to your agent.
Alex Shaw: 9:33 So you’re either running your agent outside the sandbox and executing commands into it, or you’re running it inside the sandbox and it’s calling whatever its commands are as part of its program.
Alex Shaw: 9:46 Um, and then it runs for some amount of time until it hits a stopping condition, produces some trajectory—and we’ll come back to that later because that’s important.
Alex Shaw: 9:54 And then you pass that sandbox to the verifier, which, uh, runs some verification process.
Alex Shaw: 10:00 And then finally, you stop the sandbox, the verifier produces a reward or a set of rewards, and then you take those, you aggregate them a bunch across a bunch of rollouts in a data set with some agent, and that becomes your eval result.
Alex Shaw: 10:21 So this process here, which looks relatively simple, is actually extremely universal. And, uh, it’s also a little bit overly simplified, so Harbor by now allows for a lot of different flavors of rollouts—so you can do multi-step, you can run your verification in a separate sandbox, you can collect artifacts, you can simulate a user—but this is kind of like the, the barebones approach, uh, that they’re all built off of.
Alex Shaw: 10:44 So what is Harbor more specifically? One, it’s a format for specifying agentic environments. Two, it’s an open-source framework for performing rollouts in parallel using any agent with any model in any sandbox on any task.
Alex Shaw: 11:00 And it’s a registry of popular training and eval environment sets. I think we have like three or four hundred eval sets by now. And in fact, I think two or three benchmarks even came out today that run with Harbor.
Alex Shaw: 11:18 Um, so we’re excited about that. And in general, it is trying to be a common language for environments, so a way for people to specify things that are extremely interoperable and it allows you to maximize data velocity and just increases progress in the industry.
Alex Shaw: 11:35 Uh, so who needs evals? Now that we understand how to make them, we understand how to use them, well now who should actually be doing this? And the answer is every single company that uses computers.
Alex Shaw: 11:49 And I think that’s probably close to all of the companies in the world. And the reason is because if you’re doing something on a computer, then you should be seeing if you can use AI to automate part or all of that process that you’re currently performing on a computer, uh, because that will increase the productivity of your company and therefore increase the value that your company generates.
Ryan Marten: 12:00 Start with the eval that matters and your ability to grade that outcome and then say I welcome all models. So I like that last line because what he goes to say is that as soon as you have an eval the power is now in your hands. You can consider every single model. You don’t have to trust brand. You don’t have to trust somebody else’s eval. You don’t have to trust a public eval, um, and you can kind of skate the Pareto however you desire to, uh, balance that cost performance tradeoff.
Alex Shaw: 12:12 Uh, so I like this quote from Satya Nadella from the Applied Compute podcast he did last week. He says, if you want to build an agentic system—
Ryan Marten: 12:30 So step one build the eval and step two kind of optimize against it.
Ryan Marten: 12:34 Um so what will people evaluate and um I’m going to list four things and these four things are based off of what we actually see people using Harbor to build evals for right now. Uh so so the first type of eval is people evaluating how well agents build their products. So everybody that’s building a software product has some internal codebase or set of internal codebases. Uh I think Ramp recently announced like Ramp SWE-bench which is a SWE-bench built off of their internal codebase and what that allows them to do is pick the coding agent or the model that performs best on their internal use cases and they don’t have to, you know, maximize token spend instead they can make informed and educated decisions about how they build their products with agents.
Ryan Marten: 13:21 The second type of eval that we see people build is how to evaluate uh how well agents use your product. So anybody that builds a software product is probably moving towards a world where they offer some sort of headless mode. So you see some companies have always been this way. They’ve been developer first like uh HubSpot and Stripe and things like that. And the idea is uh if you can make an eval to see how well agents use your product and then iterate on your product to make it more usable for agents, you’re going to get more usage and therefore your product uh will become more valuable to agents.
Ryan Marten: 13:57 And then three evaluate how well agents power product features.
Ryan Marten: 14:02 And then four evaluate how well agents automate internal processes. So depending on what type of company you are uh one or more of these might apply to you but everybody should be considering right now how they can do one of these things.
Ryan Marten: 14:14 Uh okay so what are the different use cases of the Harbor rollout? So we’ve talked about evals, that’s the most popular right now. Um… oh…
Ryan Marten: 14:26 Oh here we go I actually have a video even of us doing an eval in Harbor. So this is uh how you can run it from the command line or have your agent run it from the command line. So you can see here it says Harbor run, we’re running in this case Terminal Bench 2.1 with Codex and GPT-3.5 and we’re saying let’s run 64 in parallel. And then we actually type in the launch command right here which is something we’re rolling out soon which allows you to launch the rollouts on Harbor servers which means you can just fire and forget and go to sleep and then come back the next day and…
Alex Shaw: 15:00 10,000 rollouts are done for you. And you can kind of see and hear what it looks like to look at those rollouts happening. But they don’t complete in the time span of this video because rollouts can take a while, which is another case for parallelizing as much as you possibly can to tighten that loop and maximize your throughput.
Alex Shaw: 15:21 So there are people who create tasks and sell those as data. So there’s actually like a multi-billion dollar market right now that exists probably around Harbor data and also other types of data. But it’s very, I guess, lucrative right now where experts can specify certain types of tasks that they would like automated and then sell those to one of the labs that’s training models to improve on that capability.
Alex Shaw: 15:51 You can also do what we call prod rollouts. So remember Harbor is evaluate any agent with any model. I guess not even evaluate, we’ll just say run any agent with any model in any sandbox on any task. And that actually doesn’t mean you have to do it for evaluation. It also doesn’t mean you have to do it for training. It could literally be that you want to do what we’ve been calling agentic map-reduce, which is you just want to run a ton of agents on distributed compute, so sandboxes, in parallel and then somehow aggregate those results, probably also intelligently.
Alex Shaw: 16:34 So things like looking over a bunch of trajectories to detect reward hacking, or I don’t know, like processing a bunch of receipts for reimbursements, or searching over your Obsidian files to figure out semantically what… where you wrote some note, or processing a bunch of PRs to ask a question about it. So we see a bunch of different use cases. This is actually an emergent use case. So we didn’t build Harbor for this, but we see people doing it a lot. So we actually built this feature and launched it just for this. So it’s Harbor Exec. It’s going to go away kind of soon, but you can see in this scenario, actually let me see if I can pause this.
Alex Shaw: 17:13 So I’m actually going to go back a little bit before we kicked it off. So I’m saying Harbor Exec input is all of my Codex sessions from the June 20s. And then I say prompt ‘if I corrected the agent right in analysis.json with mistake reason and correction’. And then my reduce prompt is ‘summarize recurring mistakes and failure categories into a concise feedback.md file’. And then you can see in this case I’m running on Modal. I do the map step with Cursor CLI because it’s cheap and fast. And then I do the reduce step with Claude 3.5 because I want it to have like an accurate summary and I care about intelligence in that scenario.
Alex Shaw: 17:49 So and then I’m limiting it to 32 because I didn’t actually want to process all of my sessions for this demo. But you could… there’s no reason you couldn’t do like 10,000 sessions or 1,000 sessions. And then maybe you have to go and understand the results more deeply. But um… oh shoot. But yeah you can kind of see here…
Alex Shaw: 18:00 I think so we kick this off a bunch of these rollouts are in parallel. This one is running locally on my computer with like cloud sandboxing but orchestrated locally.
Alex Shaw: 18:11 And then you can see here all of the cursor rollouts running right now, but those will take a second to finish.
Alex Shaw: 18:18 And then you can see the reduced step here where Fable recommended me like recurring mistakes. And like these recurring mistakes, for example, could be used to inform the next batch of Harbor tasks that I create to evaluate my agent and pick like a better agent or train up a skill or something like that.
Alex Shaw: 18:32 So another use case of Harbor. And then we see people taking the trajectories and doing SFT. And then we also see people taking the reward or rewards, the trajectory in the form of tokens, and doing actual reinforcement learning.
Alex Shaw: 18:51 For example, Thinker launched an integration with Harbor, and then people also do other types of optimization, so we mentioned Japa, but any of these like evolutionary methods, you take the text feedback in the form of a trajectory and the eval and you can do some sort of like auto-hill climbing with a harness or a skill.
Alex Shaw: 19:12 Um, so in the last couple minutes I just want to talk about some cool things people have built with Harbor. I’ll try to breeze through this.
Alex Shaw: 19:19 So Frontier Suite, an ultra-long horizon software engineering benchmark built on Harbor. Banker Toolbench, an investment banking benchmark built by Handshake on Harbor.
Alex Shaw: 19:31 Swyx saying that his team at Cognition migrated all their evals to Harbor.
Alex Shaw: 19:36 This RuneBench, this is one of my favorites, it’s like a benchmark to measure how well agents can play RuneScape.
Alex Shaw: 19:43 Scale launched their whole Atlas suite on Harbor.
Alex Shaw: 19:47 Poolside uses Harbor to do all of their evaluations for model training.
Alex Shaw: 19:52 Kevin Goo created AutoAgent, which is a self-optimizing agent that all you have to plug in is a Harbor eval.
Alex Shaw: 19:58 Afterquery post-trained a model using Harbor.
Alex Shaw: 20:01 Cognition released Frontier Code recently which is a Harbor benchmark.
Alex Shaw: 20:05 And LangChain just integrated DeepAgents and their sandboxes into Harbor.
Alex Shaw: 20:11 And then actually just today, Snorkel released Senior SWE-bench, which is a benchmark for measuring how well agents can function under ambiguity with behavioral feedback.
Alex Shaw: 20:22 So that’s kind of a brief overview of Harbor and the different things you can do with it. I would encourage everybody here to check it out.
Alex Shaw: 20:28 And then this is a link to my Twitter and the reason I’m linking my Twitter, usually I link Harbor docs, but we’re actually actively trying to grow the Harbor team right now.
Alex Shaw: 20:40 So if you want to get involved, then shoot me a DM on Twitter, and if you just want to see the docs then click the docs link on my Twitter and that’s the best way to get there.
Alex Shaw: 20:50 So thank you very much.
Note: The source audio contains an unrelated podcast trailer (“The Puppet Master”) appended after the talk’s closing line at 20:50; it has been omitted from this transcript as it is not part of Alex Shaw and Ryan Marten’s presentation.