Why Large? Tiny LMs & Agents on Edge/Robotics — Cormac Brick, Google
Why Large? Tiny LMs & Agents on Edge/Robotics — Cormac Brick, Google
Summary
Cormac Brick, tech lead on Google’s AI Edge team, argues that the binding constraint on edge AI isn’t compute — it’s DRAM, and it’s getting worse: phone makers are shipping less RAM this year than last, and a Raspberry Pi’s memory has gotten 2.5x more expensive since launch. That single fact shapes everything else in the talk. His team ships open-source runtimes (LiteRT-LM, LiteRT-MediaPipe) that make it possible to run AI on edge devices, and works with the Gemini team to make sure models actually run well across that hardware. Small models — his term for roughly 1-4 billion parameters, like the 2-billion-parameter Gemma — already ship inside Android’s AI Core and Apple Intelligence, and Brick’s team squeezes them down to as little as 2.9 bits per weight via mixed quantization, getting a text-only model into 841MB. On a Raspberry Pi that yields about 7.6 tokens/second decode; on a Jetson Orin Nano, up to 24 tokens/second; on a Qualcomm NPU, nearly 4,000 tokens/second prefill and 31 tokens/second decode — fast enough for a few frames of vision per second, which he demonstrates via the open-source Open Duck Mini V2 hobby robot.
Below small models sit “tiny” models — 50 to 500 million parameters — needed to reach devices where even a small model won’t fit: older laptops, cheap consumer electronics, or cases where the model is a minor feature running alongside everything else in an app. The playbook here is fundamentally different: small models work fine with zero-shot prompting, but tiny models generally need fine-tuning to be reliable. Off-the-shelf tiny models already cover ASR, vision, and embeddings well (he cites Apple FastViLM running fast on Android). For everything else, Brick’s team fine-tunes tiny Gemma variants — Gemma 2B and Function Gemma — on synthetic datasets of 10,000 to 10 million samples, which reliably matches or beats the quality of a much larger model on a narrow task.
The payoff example is voice-to-function calling: a fine-tuned Function Gemma model recognizes about 10 device actions (toggle Wi-Fi, schedule a calendar event) from arbitrary free text at over 86% reliability, jumping to 45 tokens/second decode on a Raspberry Pi because there’s less to read from memory. Pairing it with a speech model gives voice-to-function calling, which Brick frames as a key answer to unusable settings menus on small devices. The most concrete production example is an offline, subscription-free voice dictation app built on two sub-billion-parameter fine-tuned Gemma models — one for ASR, one for text polishing — that also cleans up “ums” and “ahs” and personalizes to the user’s vocabulary, entirely on-device.
Highlights
”DRAM cost really casts a shadow over the rest of this talk”
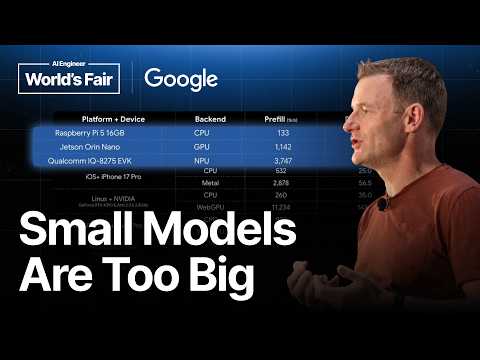
“The main challenges of deploying AI on the edge, the leftmost one is kind of new, which is DRAM cost. And it’s a really significant constraint… you’ll even see some mobile phone manufacturers are putting less DRAM into their devices this year than previously. You’ll also see that since launch, the cost of a Raspberry Pi 3 16 gigabytes has gone up by a factor of like 2.5x.” — Cormac Brick, 3:23
Clip command
yt-dlp --download-sections "*3:23-4:03" "https://www.youtube.com/watch?v=hacEQHHhu2Q" --force-keyframes-at-cuts --merge-output-format mp4 -o "dram-cost-constraint.mp4"Gemma at 2.9 bits per weight
“So it uses a mix of like two-bit, four-bit and eight-bit quantization, getting it down to like, I think they’re like 2.9 bits per weight if you look at the actual weights we need to hold in memory.” — Cormac Brick, 6:43
Clip command
yt-dlp --download-sections "*6:43-7:29" "https://www.youtube.com/watch?v=hacEQHHhu2Q" --force-keyframes-at-cuts --merge-output-format mp4 -o "gemma-2point9-bits.mp4"The Open Duck Mini robot, on a Raspberry Pi vs. a Jetson
“The Jetson Nano one performs has really good real-time interaction, the one based on Raspberry Pi it works but it’s kind of a lot slower, right? So for some examples, for some types of interaction, even the kind of best models we have today are maybe not meeting a kind of user interaction requirements.” — Cormac Brick, 10:58
Clip command
yt-dlp --download-sections "*10:58-11:26" "https://www.youtube.com/watch?v=hacEQHHhu2Q" --force-keyframes-at-cuts --merge-output-format mp4 -o "open-duck-robot-speed-gap.mp4"86% reliable voice-to-function calling on a fine-tuned tiny model
“This model knows about 10 different output functions and can call them at over 86% reliability from a given arbitrary text input. And this is for doing common things on a mobile device, like schedule a calendar or turn on and off Wi-Fi or things like this.” — Cormac Brick, 15:20
Clip command
yt-dlp --download-sections "*15:20-15:46" "https://www.youtube.com/watch?v=hacEQHHhu2Q" --force-keyframes-at-cuts --merge-output-format mp4 -o "voice-to-function-calling.mp4"Offline voice dictation with no subscription
“The backbone of this app is kind of two fine-tuned small Gemma-based models in the low single-digit hundreds of… billion parameters… it happens locally on device, and as well as just doing dictation it also cleans up ums and ahs, and it’s also able to do biasing towards words and names that are relevant to you personally.” — Cormac Brick, 18:00
Clip command
yt-dlp --download-sections "*18:00-19:05" "https://www.youtube.com/watch?v=hacEQHHhu2Q" --force-keyframes-at-cuts --merge-output-format mp4 -o "offline-voice-dictation.mp4"Key Points
- The talk’s scope (0:12) - State of the art of tiny models: what they’re good at, and what you can build today, versus the higher-end robots covered in earlier talks.
- Google’s AI Edge team (1:14) - Builds open-source LiteRT-LM and LiteRT-MediaPipe, ships edge AI into Google’s own products, and works with the Gemini team on wide device support.
- Why edge AI at all (2:32) - Latency, privacy (data stays on-device), offline availability, and cost savings versus calling a cloud model at scale.
- DRAM is the real constraint (3:23) - Phone makers shipping less RAM; Raspberry Pi memory up 2.5x in cost since launch; forces heavy quantization work.
- The under-studied lower end (4:03) - Most LLM research hours go into larger models and MoE techniques; the small end of the spectrum gets far less attention.
- Small models defined (4:44) - Roughly 1-4B parameters; ship inside Android AI Core and Apple Intelligence; need 4-8GB DRAM; playbook is mostly zero-shot prompting or LoRA.
- Gemma 2B quantized to 2.9 bits/weight (6:43) - Mixed 2/4/8-bit quantization plus per-layer embeddings gets the model to 841MB of weights, ~2GB active RAM with runtime and KV cache.
- Decode speed across hardware (7:36) - ~7.6 tok/s on Raspberry Pi, ~24 tok/s on Jetson Orin Nano, ~31 tok/s decode / ~4000 tok/s prefill on a Qualcomm NPU.
- NPU speed enables near-real-time vision (8:29) - At ~500-1120 tokens per image, the Qualcomm NPU numbers translate to roughly 3 frames per second of high-resolution vision.
- Try it yourself: AI Edge Gallery (9:29) - Open-source iOS/Android app for benchmarking small models on your own phone.
- Open Duck Mini V2 robot (10:19) - Hobby robot built by a DeepMind engineer; compares Jetson Nano vs. Raspberry Pi for voice/image-reactive behavior.
- When small models are still too big (12:00) - Older laptops, lower-tier consumer devices, and cases where the model is a minor feature running alongside everything else.
- Tiny models defined (12:40) - 50-500M parameters, under 2GB RAM, can run very fast, but need a more complex deployment playbook.
- Off-the-shelf tiny models (13:29) - ASR, vision, and embedding models work well out of the box; Apple FastViLM (0.5B) cited as a fast on-device vision example.
- Fine-tuning tiny Gemma variants (14:30) - Gemma 2B and Function Gemma (270M+) as starting points; fine-tuning jumps Raspberry Pi decode speed to 45 tok/s.
- The synthetic data playbook (16:33) - 10,000 to 10 million synthetically generated samples is generally enough to fine-tune a tiny model to high reliability; the “Mobile Actions” dataset is open-sourced on Hugging Face.
- Matching larger models on narrow tasks (17:26) - A fine-tuned tiny model can match or exceed a 2-4B model’s quality on tasks like summarization or proofreading, at a fraction of the size.
- Production example: offline voice dictation (17:49) - Two fine-tuned sub-billion-parameter Gemma models (ASR + text polishing) replace what used to be a subscription cloud feature.
- Chrome’s built-in AI APIs (19:05) - Summarization and proofread APIs in Chrome developer preview are powered by tiny models so they can ship to far more users.
- Takeaways (19:28) - Small LLMs are fast and easy, especially on NPUs; tiny models reach a much larger device pool; voice-to-function calling is now robustly buildable with the right synthetic dataset.
- Q&A: generalizing voice-to-function calling (20:27) - Brick’s stated goal: have an agent generate the synthetic training data itself, making the whole approach much easier to replicate.
Mentions
Companies
- Google (1:14) - Cormac Brick’s employer; AI Edge team ships LiteRT and works with the Gemini team.
- DeepMind (10:19) - Engineer “Xavier” built the Open Duck Mini V2 robot as a hobby project.
- Apple (4:44) - Apple Intelligence cited as shipping a small on-device model; FastViLM cited later as a fast tiny vision model.
- NVIDIA (8:00) - Jetson Orin Nano hardware; NVIDIA’s own tool chain can decode even faster than Google’s.
- Qualcomm (8:11) - IoT board Google’s team ported models to, popular in higher-end robotics and IoT.
Products & Technologies
- LiteRT-LM / LiteRT-MediaPipe (1:14) - Google AI Edge’s open-source runtimes for deploying models to edge devices.
- Gemma 2B (6:05) - The team’s go-to small model example; quantized to 2.9 bits/weight for edge deployment.
- Function Gemma (14:30) - Gemma variant with extra pre-training for function-calling; starting point for the voice-to-function-calling demo.
- Mobile Actions dataset (16:33) - Open-sourced synthetic dataset on Hugging Face for recreating the fine-tuned function-calling demo.
- AI Edge Gallery (9:52) - Open-source iOS/Android app for trying small models on-device.
- Open Duck Mini V2 (10:19) - Open-source hobby robot demoing voice/image reactive behavior on Jetson Nano vs. Raspberry Pi.
- Apple FastViLM (13:29) - 0.5B-parameter vision model running fast on Android with hardware acceleration.
- Chrome built-in AI APIs (19:05) - Summarization and proofread APIs in developer preview, powered by tiny models.
People
- Cormac Brick (1:14) - Speaker; tech lead on Google’s AI Edge team.
- Xavier (10:19) - DeepMind engineer who built the Open Duck Mini V2 robot as a hobby project.
Surprising Quotes
“Since launch, the cost of a Raspberry Pi 3 16 gigabytes has gone up by a factor of like 2.5x.” — Cormac Brick, 3:23
“The lower end of the LLM spectrum is a lot less studied.” — Cormac Brick, 4:03
“Even the kind of best models we have today are maybe not meeting a kind of user interaction requirements.” — Cormac Brick, 10:58
“In the range of 10,000 to 10 million samples of synthetically generated data will be sufficient to fine-tune a smaller model to a really, really high degree of reliability.” — Cormac Brick, 17:00
“If we can figure out how to make… have like an agent generate the synthetic data for you… it’s certainly possible to make that journey much easier than it is today and make it available to a lot more people.” — Cormac Brick, 20:27
Transcript
Cormac Brick: 0:12 Yeah, so yeah, bit of a change of speed from the last two talks where we’re looking at kind of higher end robots. If we want for intelligence to get into lots and lots and lots of devices and not just really expensive robots, we are going to need tiny models. And this talk is about what is the state of the art of tiny models at the moment, what are the things they’re good at, and what are the things you can go start building today.
Cormac Brick: 0:39 Okay. So yeah, firstly a bit of background like briefly on me and and the team I work on. Then we’re going to take a look at small models that you may be kind of more familiar with just kind of explore what they can do, what they can’t do yet, and then kind of see hey, why do we need even smaller models? And then just looking at the state of the art of tiny models today and what you need to do to get them into a form where you can deploy them in production to do useful things. And yeah, lastly we’ve a couple of examples that we can look at from work from our team.
Cormac Brick: 1:14 Okay, um so me, I work I’ve worked in um edge AI for a while. Um these days I work as a tech lead um on the AI edge team at Google. Within the team, the types of things we do um are we develop kind of open source projects called like LiteRT-LMM, LiteRT-MediaPipe, and these make it easy to deploy AI to edge devices. We also do a lot of work delivering kind of edge AI core technology to Google’s own products, um some of which would be via tiny models. And then we also work with the Gemini team to ensure their models work well on um and run well on lots of devices. And then we have a significant focus on small and tiny models because that’s what um that’s what’s useful um for a lot of kind of mobile phone applications or if we want to be able to ship a model in browser, um that also has to be really really small. And generally our kind of playbook is we develop things for first party use like for in-house use first and then if we can figure out a way to share that via an open source package or make those tools available to the wider world, we we do so and that helps kind of lots of other people um build similar types of things using open source technology.
Cormac Brick: 2:32 Okay, so why do edge AI? It’s probably like um relatively as opposed to just doing everything in the cloud. Um you know, kind of obvious, but I’ll kind of go through it anyway. There’s like kind of latency, you’ve fast consistent speed, privacy, data stays on the device, offline use, it’s kind of reliably available, so that kind of um that feature that you rely rely on on your mobile device will still work even when you don’t have reception. That can be very helpful. And then savings, um especially these days if the alternative is to call a
Cormac Brick: 3:00 Even a faster model on the cloud, that will come at a cost. Particularly if you’re kind of shipping an app or like a mobile phone app or something in-browser where, you know, the user interaction is at kind of a very, very large scale then, even though those tokens are relatively cheap, you’re multiplying it by a large number and it’ll add up quickly.
Cormac Brick: 3:23 So then, um, the main challenges then of deploying AI on the edge, the leftmost one is kind of new, which is DRAM cost. And it’s a really significant constraint that… and you’ll even see some mobile phone manufacturers are putting less DRAM into their devices this year than previously. You’ll also see that since launch, the cost of a Raspberry Pi 3 16 gigabytes has gone up by a factor of like 2.5x. So DRAM cost is really, really significant. That then has a, like, casts a shadow over the rest of this talk, right? Where in order to be able to get AI applications running on the edge, we need to really think a lot about quantization, we also really need to think about what is the smallest possible model we can use for a given task.
Cormac Brick: 4:03 Other challenges are, yeah, there’s a wider pool of target devices. And yet another challenge is… yeah, it’s kind of fair to say that a lot of the research hours that go into LLMs these days are into the much larger models and MOE techniques and this type of stuff. And the lower end of the LLM spectrum is a lot less studied. So yeah, these are challenges of deploying on the edge.
Cormac Brick: 4:44 Okay, so small models, and when I say small, I mean kind of typically maybe kind of 1 to 2 or 1 to 4 billion parameters. You may find that these are built into the OS, there’s a version of a small model that ships in Android high-end phones today with AI Core, there’s a version that ships with Apple with Apple Intelligence. Some app vendors will ship a model this size in their app, we certainly work with some app vendors that do this. And for like IoT and robotics, you would typically require like 4, maybe 4 to 8 gigs of DRAM in order to be able to ship this grade of model, which then has an implied cost on the device, right? So then it kind of restricts these models to, you know, things like laptops, mobile phones or kind of higher-end electronics and kind of puts it out of reach of maybe a lot of lower-tier web browsers or the wider kind of IoT and consumer robotics market. Yeah, and for smaller models, developing smaller models, and we’ll look in a while, we do a lot of work to minimize footprints with kind of quantization. And the playbook here is mostly prompting, right? If you want to deliver a particular feature using a smaller model, you can just kind of use zero-shot prompting and get pretty good performance, also to use LoRA adaptation.
Cormac Brick: 6:00 …and it’s kind of somewhat robust to doing things like kind of function calling and agent skills.
Cormac Brick: 6:05 Okay. So really quick example is like our, you know, in working with the Gemma team, our favorite go-to example is always Gemma for these kind of things.
Cormac Brick: 6:14 Uh, so we can see that like the 2B model is, um, pretty capable in terms of reasoning, it’s certainly like on par like with a Gemini 1.0 much larger model from kind of 12 months ago.
Cormac Brick: 6:26 And, yeah, so we now have like much smaller models with that were pretty capable at reasoning and we get pretty decent answers just with zero shot prompting for a given task.
Cormac Brick: 6:36 We’ve also done lots and lots of work to optimize the memory footprint of that two billion parameter model as much as we possibly can.
Cormac Brick: 6:43 Um, so it uses a mix of like two-bit, four-bit and eight-bit quantization, getting it down to like, I think they’re like 2.9 bits per weight if you look at the actual weights we need to hold in memory.
Cormac Brick: 6:54 We do other tricks like per layer embeddings. I won’t go into like all of the detail here, but end result is we can, you know, you need maybe one, like here it’s 841 megabytes for a text only model in memory just for the weights.
Cormac Brick: 7:05 And then, you know, maybe by the time you add in the runtime, a KV cache, a footprint, you might be up to requiring like two gigs of active RAM to be able to run this model.
Cormac Brick: 7:17 Then you account for an OS and the fact that there’s other things going on, that’s where we get the kind of four, four gig plus rule of thumb for deploying this on a device.
Cormac Brick: 7:29 Um, then in terms of speed, this is using our runtime, this is just a list of devices that we run on.
Cormac Brick: 7:36 For the purpose of this talk, we’re going to look more closely at the last three rows of the table, which is if we take that two billion parameter model and run it on a Raspberry Pi, um, that is will give about 7.6 tokens per second decode.
Cormac Brick: 7:52 This is without MTP. If you turn on MTP that’ll get maybe 2X faster depending on the task.
Cormac Brick: 8:00 Um, if you go to a higher, a more capable device like a Jetson Orin Nano, we can get up to maybe 24 tokens per second decode or maybe even faster if you use NVIDIA’s own tool chain, this is with our tool chain.
Cormac Brick: 8:11 We also have done work to port this to a Qualcomm IoT board which is pretty popular among kind of higher end, uh, robotics and IoT applications.
Cormac Brick: 8:21 And there, yeah, you can see you can get about like almost 4000 tokens per second pre-fill, 31 tokens per second decode.
Cormac Brick: 8:29 And that’s useful for lots of like almost real-time applications on an NPU because, um, with these, uh, with Gemma-2 models, like one medium resolution image is like kind of 500 tokens, a high resolution image is 1120 tokens.
Cormac Brick: 8:44 So you could get like, you know, three frames per second of high, high resolution tokens going through this model and have pretty decent decode speed as well.
Cormac Brick: 8:54 So there’s lots of, lots of compelling applications you can build with this type of, with a small model if you’re kind of, if you’re into that.
Cormac Brick: 9:00 your kind of market or if you’re kind of willing to have more expensive hardware and have a more expensive DRAM kind of line on your kind of bill of materials for the device you’re building.
Cormac Brick: 9:17 yeah just like our tool chain we also work with other models in the community that are of similar size and they each have their strengths as well, right? so these are some of the other models that we support here.
Cormac Brick: 9:29 really briefly I won’t go into this in too much detail but we also… if I can get this to play… we also have an app that you can use on both iOS and Android so if you want to take one of these small models see how fast it works on a phone you can just go straight ahead and do that.
Cormac Brick: 9:52 so it’s available on AI edge gallery also all of the… oh my god that buzzing… all of the app is also fully open source so if you want to see how to build something similar using one of these models or to see how this is using the open source runtime that runs a models you can see all of that. so this is a great way of just getting started and trying small models if this is what you want to do.
Cormac Brick: 10:19 okay this is another example which I’m not going to play this video but you should definitely check it out. this is an example showing a open source the Open Duck Mini V2 robot. this is one Xavier one of the engineers in DeepMind built this as a kind of hobby project. really really fun.
Cormac Brick: 10:38 so go check out this YouTube video. what you’ll what you’ll see is you see two robots, one is one uses the Jetson Nano, one uses the Raspberry Pi and you’ll see that the robot is able to it’s able to kind of like read signs like and react to things and kind of nod its head it’s also kind of able to take both a voice and image input.
Cormac Brick: 10:58 yeah and what you’ll see is the Jetson Nano one performs has really good real-time interaction the one based on Raspberry Pi it works but it’s kind of a lot slower, right? so for some examples for some types of interaction even the kind of best models we have today are maybe not meeting a kind of user interaction requirements.
Cormac Brick: 11:19 but yeah this is a really fun video so definitely check it out.
Cormac Brick: 11:26 so then small models while they’re great right if your product can afford to use one of these they’re they’re really easy to use because you just need to zero-shot prompt in order to get it to work. Gemini’s done great work in having you know low footprint high capability models that are ready to use and they’re optimized running on all of those devices you saw earlier and if yeah so if all of your if you can live within those constraints then great right your journey will
Cormac Brick: 12:00 stop here and you would build a feature you would want, right? For lots and lots of other things that we do in our work and other people that we talk to, you know, we’re still at a point where small models are too big because they can’t reach like older laptops or kind of more consumer edge devices.
Cormac Brick: 12:19 The user interaction needs to be more responsive. We also could have the reality and we do have this a lot of times where the model you want to run isn’t the main feature in the application, it’s like one tiny little thing in a corner that needs to run while everything else in the system is running. So we also need a smaller model for system health as a common common pattern.
Cormac Brick: 12:40 So then enter kind of tiny models, right? So these are typically in the as small as kind of 50 million parameters, we’ve deployed models that small to maybe 500 million parameters. They’re easier to ship natively with applications. They would run on the types of things you see on the right-hand side and would require, you know, maybe less than 2 gigs of RAM or or even less than that and they can also be made to run really, really fast.
Cormac Brick: 13:10 But the playbook to deploying here, it’s a little more complicated. Uh so, you know, sometimes there’s off-the-shelf models that’ll do what you want and we’ll look at those in the next slide or else if that doesn’t work, you’re going to be left in a world of kind of fine-tuning a model to achieve a given outcome, but which works very, very well.
Cormac Brick: 13:29 So fixed task models… um there’s a bunch of things around ASR, vision, and embedding models and if you have a if you have something yeah so like ASR and vision and embeddings, these are all kind of stock features and they work really, really well. This is an example of Apple FastViLM, which is 0.5 billion parameter model running on a uh Android device using hardware acceleration. And you can see it runs really, really fast.
Cormac Brick: 13:54 So if you needed to kind of add a little bit of visual intelligence to a uh like an edge device or an IoT device, you know, this class of model is an excellent uh is an excellent option to get that kind of first level of visual awareness. Or for ASR um yeah there’s some kind of strong models listed here as well.
Cormac Brick: 14:18 And and then lastly embedding models are great at um yeah like this is just a text embedding model which is yeah really good at kind of uh processing and matching text which is can be relevant in some cases.
Cormac Brick: 14:30 Okay. Um but then next scenario is you want to kind of fine-tune a model. Um so here you can start with uh the models I’m citing here are kind of Google developed models. Uh so there’s some starting at like 270 million parameters in Gemma 2B and Function Gemma.
Cormac Brick: 14:46 Gemma 2B is a general purpose model, Function Gemma is one that has extra pre-training uh for function calling patterns. So here the performance, if you remember earlier on the Raspberry Pi our performance was at uh mid single digit tokens per second decode. So here that could…
Cormac Brick: 15:00 …jumps up to 45 tokens per second because we need to read less from memory each time. And we can fine-tune this to do pretty compelling things. So on the right-hand side, this is running a what we call a mobile actions model. So this takes text in and function calling out.
Cormac Brick: 15:20 This model knows about 10 different output functions and can call them at over 86% reliability from a given arbitrary text input. And this is for doing common things on a mobile device, like schedule a calendar or turn on and off Wi-Fi or things like this. And it can take like arbitrary free text input and convert that to appropriate function calling.
Cormac Brick: 15:46 And for this demo, we’ve taken another ASR model and put it in front of that, which gives kind of voice to function calling as a feature. And voice to function calling is pretty key for lots of IoT and edge devices because, yeah, like smaller devices tend to have, you know, require settings menus and that user interface can be really, really challenging for lots of people.
Cormac Brick: 16:10 So yeah, being able to just talk to something to ask for a given outcome, this is a pretty key capability and we can do that reasonably reliably using a fine-tuned small model. So the playbook is generally then you pick a base model, you check the performance, if the performance and memory footprint are within the range that you want.
Cormac Brick: 16:33 And then the kind of the harder part is you the playbook we’ve found works really, really well is we synthetically generate data to fine-tune that model. Depending on the model, like there’s a dataset we’ve open-sourced here called Mobile Actions, it’s available on Hugging Face that corresponds to this, if you want to kind of recreate that same demo yourself and fine-tune FunctionGemma from scratch.
Cormac Brick: 17:00 But we’ve generally found that in the range of 10,000 to 10 million samples of synthetically generated data will be sufficient to fine-tune a smaller model to a really, really high degree of reliability. And so for other tasks we’ve done, like things like summarization or proofreading, so something which you could do with a two or four billion parameter model reasonably reliably,
Cormac Brick: 17:26 if you’re willing to put the time and energy into creating a synthetic dataset and fine-tuning a model, you can achieve a similar like the same or greater quality with a model that is much, much smaller, will work on a much wider set of devices, and will be much, much more responsive. So yeah, and that’s the type of outcome we’re seeing now with just fine-tuning a model for a single task.
Cormac Brick: 17:49 And it’s a really like, yeah, we’ve found this is a really good playbook for deploying at like very wide scale. So here’s another example in this is one example in production where we have this is an app that we’ve developed for voice dictation without subscription. All of the voice dictation…
Cormac Brick: 18:00 it happens locally on device, um, and as well as just doing dictation it also does, uh, it also does, um, well, it kind of cleans up ums and ahs, right, if you see on the right-hand side it’s able to clean up text, it’s also able to do biasing towards kind of words and names that, um, are kind of relevant to you personally, so kind of personalization. The left-hand side kind of shows how we built that application. So there’s an ASR engine, and a text polishing engine, and both of these are fine-tuned versions of tiny Gemma models, and this allows us to take something that would have been a kind of like server-only feature of, you know, where you require a subscription to do highly accurate voice dictation, and have an app that’s just able to do that completely offline with very, very good quality. Uh, so this is something you can try on iOS if you want to give this a go today, but, um, uh, yeah, and it just, the backbone of this app is kind of two fine-tuned small Gemma-based models in the low single-digit hundreds of parameters, billion parameters, yeah.
Cormac Brick: 19:05 Also worth noting is there’s also kind of features in developer preview in Chrome, for example, that kind of summarization and proofread APIs are featured as built-in APIs in Chrome, and delivering those features via tiny models allows, um, the Chrome team to ship them to a much wider set of Chrome users than would otherwise be possible.
Cormac Brick: 19:28 Uh, yep, so that’s, we’ve probably got about like one minute for questions. Uh, some kind of key takeaways, it’s on the last slide if I can get there. Yeah, so takeaways from consumer devices and entry-level robotics is small LLMs are easy to use in and especially on NPUs, they’re very, very fast. Uh, tiny models will allow reaching a much, much larger pool of devices, and voice-to-function calling can now be built to be robust using tiny models. It just requires kind of investing in an appropriate synthetic dataset with enough samples, and then you can fine-tune a model to get really good outcomes. Cool, so…
Cormac Brick: 20:02 happy to take one or two questions or if anybody has one… Yeah.
Cormac Brick: 20:13 Sorry, I’m going to plug this out. Yeah. Sorry. Sorry, again?
Cormac Brick: 20:27 Like broader ambitions of where tiny models can go? Well, I think kind of generalizing voice-to-function calling is a is a one key goal, like making that very easy for lots of people because I think that’s a key use case that if we can figure like if we can figure out how to make, you know, have like an agent generate the synthetic data for you, right? Um, if we, like it’s certainly possible to make that journey much easier than it is today and make it available to a lot more people. Um, yeah.
Cormac Brick: 21:00 And certainly the visual input as well, and that takes a little bit of time at the moment. There’s certainly scope to have faster models there that can do a wider set of things, like kind of segmentation and other things, which would enable other use cases.
Cormac Brick: 21:12 Awesome. Yeah, due to the time, we probably don’t have enough time for the Q&A session for today. Yeah, but Cormac will stay after this session maybe, and you can ask for more questions about it.
Cormac Brick: 21:21 I’ll stay after the session or you can come grab me downstairs at the OpenVINO booth at four o’clock. I’ll be there four to five. Okay?
Cormac Brick: 21:27 Okay.